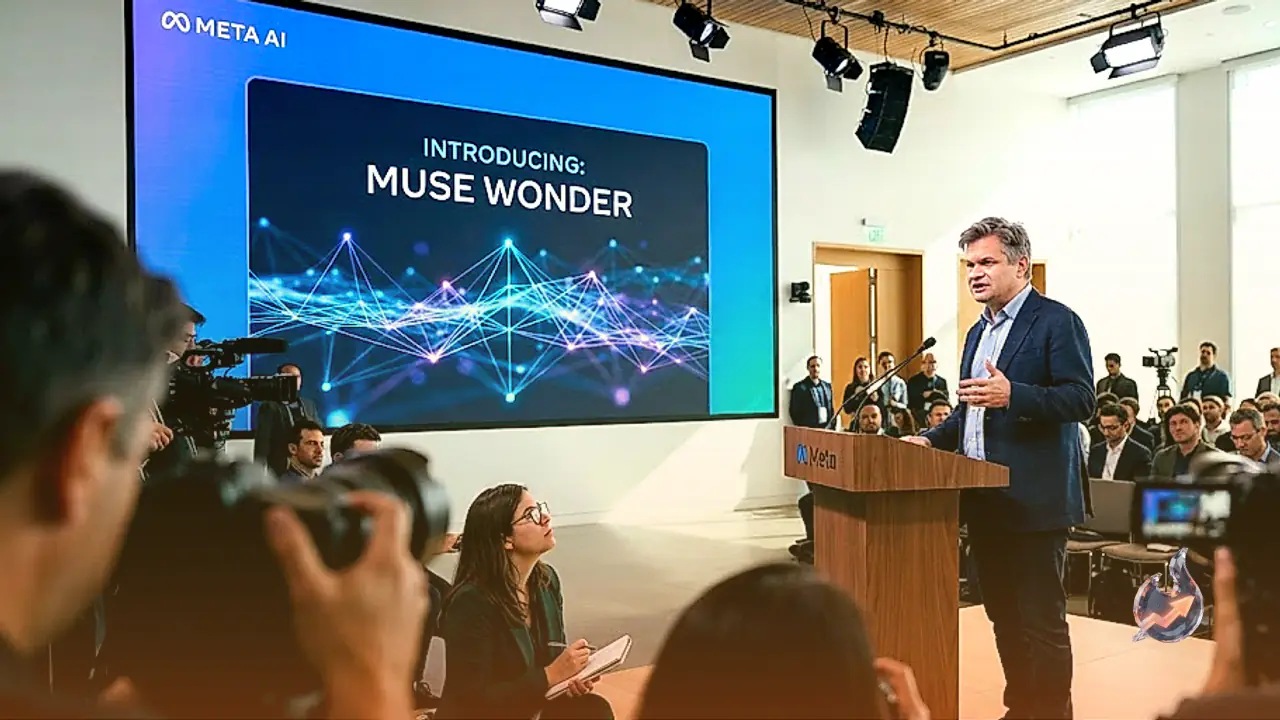















Meta has revised its commercial terms of use by removing a provision that previously triggered intense discussions among publishers and legal experts. The updated terms initially stated that the company could utilize content from any business account domains, web pages, or URLs to develop, improve, research, train, and maintain the integrity of Meta products and services.
Legal experts consulted by industry analysts pointed out that this appeared to be a significant provision. It seemingly granted Meta the legal permission to scrape the website of any publisher possessing a Meta business account and subsequently feed that content into the company's AI training pipelines. Although Meta successfully defeated a high-profile lawsuit concerning copyright infringement related to AI training last year, numerous other legal challenges against major technology firms remain active in the courts.
Following widespread scrutiny, a Meta spokesperson posted on X insisting that the revised commercial terms did not signal any fundamental shift in how the company crawls the open web. Shortly after those discussions, the contentious provision was completely stripped from the document, addressing the core anxieties raised by digital publishers.
In an official statement addressing the matter, the company emphasized that they listened to the feedback and wanted to clear up any misunderstandings. Meta explained that the consolidated crawling terms were strictly intended for ads and business products, and they have updated the language to ensure that distinction is unmistakably clear without altering broader crawler operations.