













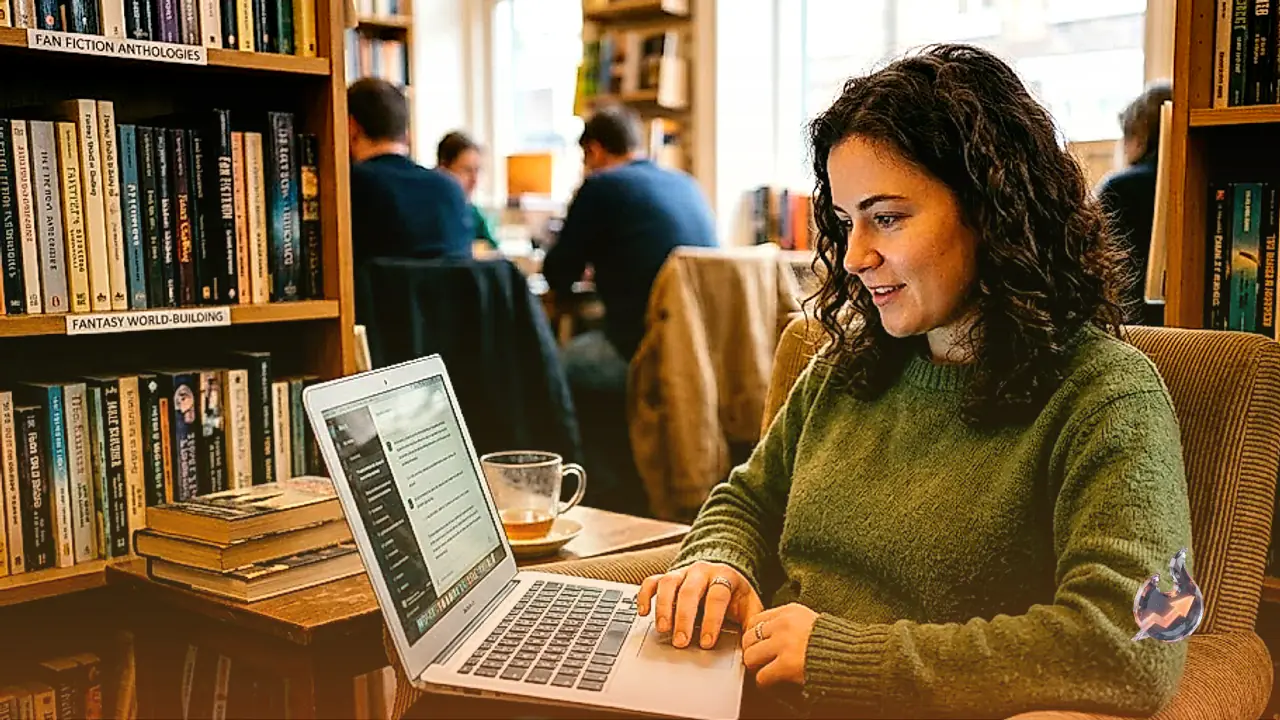
While recent discussions surrounding artificial intelligence in the literary sector have largely fixated on controversy, a quiet shift in consumer habits is underway out of the spotlight. Rather than passively absorbing narratives shaped entirely by human authors, everyday individuals are increasingly turning to generative software to steer and populate their own private story worlds. For Petra Ferraz de Novaes, a 36-year-old software engineer living in Brazil, this technological pivot became an artistic outlet. Despite nurturing a passion for storytelling since childhood, the complex mechanics of prose composition, character arcs, and sentence rhythm consistently proved overwhelming. In 2024, she turned to an artificial intelligence engine to test an unwritten idea, and she quickly grew enchanted by the machine's erratic, wandering answers. Novaes remarked that unpredictability is the core attraction, noting that the tendency of models to hallucinate turns into an asset rather than a flaw when building speculative fiction.
Today, Novaes devotes regular leisure hours to constructing elaborate digital narratives on her personal hardware through SillyTavern, an interface designed to host open-source language models locally. Her workflow begins with a rough outline or a speculative premise, such as an elven combatant battling the queen of the Amazons to take her crown, after which the algorithm supplies the surrounding exposition and dialogue. Over a single evening, she frequently navigates between distinct universes, alternating between wholly original constructs and established cultural properties like Star Wars, Pokémon, or Mass Effect. At times, Novaes crafts standalone texts that reach the length of an independent novella, which she occasionally distributes to online communities; at other times, she remains absorbed in unrecorded role-play sessions. She observes that these interactive quests feel practically infinite, with one accomplishment immediately rolling into the next whenever her imagination demands it.
Academic Analysis Uncovers Unseen Fiction Demands
This evolving pastime extends far beyond isolated experimenters, according to empirical research examining how audiences interact with large language models. Melanie Walsh, an assistant professor at the University of Washington Information School who participated in a comprehensive study on the topic, highlighted that users are fully aware of the automated origins of these texts yet remain entirely unbothered. Walsh noted that the machine origin of the material appears to form a central pillar of its appeal. The wider commercial book trade, by contrast, has recently been rocked by scandals regarding unauthorized algorithmic assistance. Major publishing houses have scrapped seven-figure advances, pulled finished manuscripts from physical distribution, and faced intense reader backlash over award-winning short fiction suspected of robotic origin. Those controversies were driven by an unstated industry assumption that commercial audiences possess no genuine desire to consume automated prose and that machine involvement cheapens the creative craft.
Walsh and her fellow researchers suggest that corporate outrage over professional shortcuts has obscured the authentic reading appetites of real consumers. By investigating a repository of more than 500,000 prompt sequences submitted to ChatGPT through the public WildChat data initiative, the research group discovered that exceeding one-third of all recorded conversational exchanges centered on creative fiction in some capacity. The inputs spanned varied creative categories, including conventional prose, verse, amateur fan fiction, adult erotica, and collaborative role-play dialogues. Although casual users occasionally request imaginative scenarios, the quantitative analysis revealed that heavy power users generate the overwhelming bulk of this volume. In one notable scenario, a solitary participant directed ChatGPT to iterate upon a single fan-fiction plotline set in the fictional universe of the visual novel Doki Doki Literature Club thousands of times across multiple months. Even when researchers mathematically isolated and removed these exceptionally heavy accounts, roughly 7 percent of the broader user base consistently engaged in generating imaginative texts.
Conflicting Methodologies and Platform Disclaimers
The conclusions drawn from the WildChat data repository carry recognized constraints. Because the archival material was compiled under rigorous anonymization protocols, researchers were unable to assemble demographic profiles detailing the age, geography, or background of participants. Furthermore, the dataset only reflects interactions from individuals who expressly consented to have their queries documented publicly, meaning the sample might not accurately mirror the worldwide population using consumer chatbots. Addressing these findings, OpenAI asserted that the WildChat catalog cannot be viewed as a representative cross-section of its broader user base. A separate academic inquiry conducted in 2025 by OpenAI alongside the National Bureau of Economic Research concluded that merely 1.4 percent of standard ChatGPT queries involved creative literature, marking a stark divergence from the university team's findings. However, that corporate inquiry excluded interactive role-play sequences, and the organization declined to clarify whether explicit adult content was counted within its baseline metrics.
Despite those empirical variances, Walsh and her research collaborators maintain that a dedicated audience of self-directed fiction creators has firmly established itself. The study identified several functional qualities that distinguish algorithmic text generators from traditional human storytellers. Language models operate entirely without personal judgment, deliver narrative continuations on command within seconds, and never suffer physical or mental exhaustion. For an audience weary of enduring creative choices made by external writers, the ability to direct plot developments, discard unwanted developments, and rapidly cycle through alternatives offers an empowering sense of agency.
The Intimacy of Tailored Erotica and Fantasy Personas
Within the genre of romantic and explicit erotica, language engines allow participants to bypass passive reading entirely by inserting themselves as active participants in direct dialogue with custom personas. Razrien, a 40-year-old resident of Indiana who opted to discuss his habits using his online handle, described the dynamic as an endless choose-your-own-adventure format with infinite variations. He utilizes local models to orchestrate elaborate power-dynamic scenarios featuring dominant non-human companions, including an irritable giant rodent partner and a towering werewolf matriarch with an explosive temper. Through iterative testing, he has mapped out the comparative behavioral tendencies of different open systems, currently selecting Google's Gemma 4 as his primary tool for romantic role-play.
Because Razrien is not currently pursuing romantic partnerships in his personal life, he views these interactive synthetic scenarios as a functional substitute that accommodates highly specific desires that mainstream digital pornography and mass-market print fiction cannot satisfy. The ability to construct tailored scenarios permits him to experience precise fantasies rather than settling for compromise material produced for mass audiences. He expresses genuine attachment to the distinct personas he nurtures through these sessions, finding emotional comfort in their predictable, programmable companionship despite the bizarre nature of the characters.
Shifting Literary Standards and Two-Tier Publishing
The proliferation of self-generated fiction has raised pedagogical questions regarding reading comprehension and cultural exposure. Some observers worry that if consumers exclusively read bespoke material crafted around their existing tastes, they will rarely encounter challenging viewpoints or stylistic variations that foster intellectual growth. Neel Gupta, a doctoral candidate at the University of Washington and coauthor of the study, argued that algorithmic generation dismantles romanticized assumptions regarding the artistic communion between author and reader. Gupta suggested that automated tools demonstrate that for a considerable portion of the public, reading functions primarily as a transactional entertainment channel focused purely on immediate gratification.
Present-day language engines still display noticeable technical shortcomings, frequently failing to produce complex character motivations, textured sentence prose, or structural coherence across full-length book chapters. As a consequence, they function most effectively when navigating predictable genres anchored in recognizable archetypes and formulaic plot structures. However, researchers anticipate that as model architectures advance, many of these mechanical hurdles will dissolve. This progression may ultimately foster a bifurcated publishing landscape, where automated and user-directed fiction fulfills the commercial entertainment needs of the median audience, while conventional human-authored literature retreats into a specialized redoubt catering to enthusiasts of aesthetic innovation and philosophical ambiguity. For early adopters like Novaes, this transformation has already rewritten her relationship with text; having previously avoided conventional novels, she now reads other people's shared AI creations as her primary form of literature.